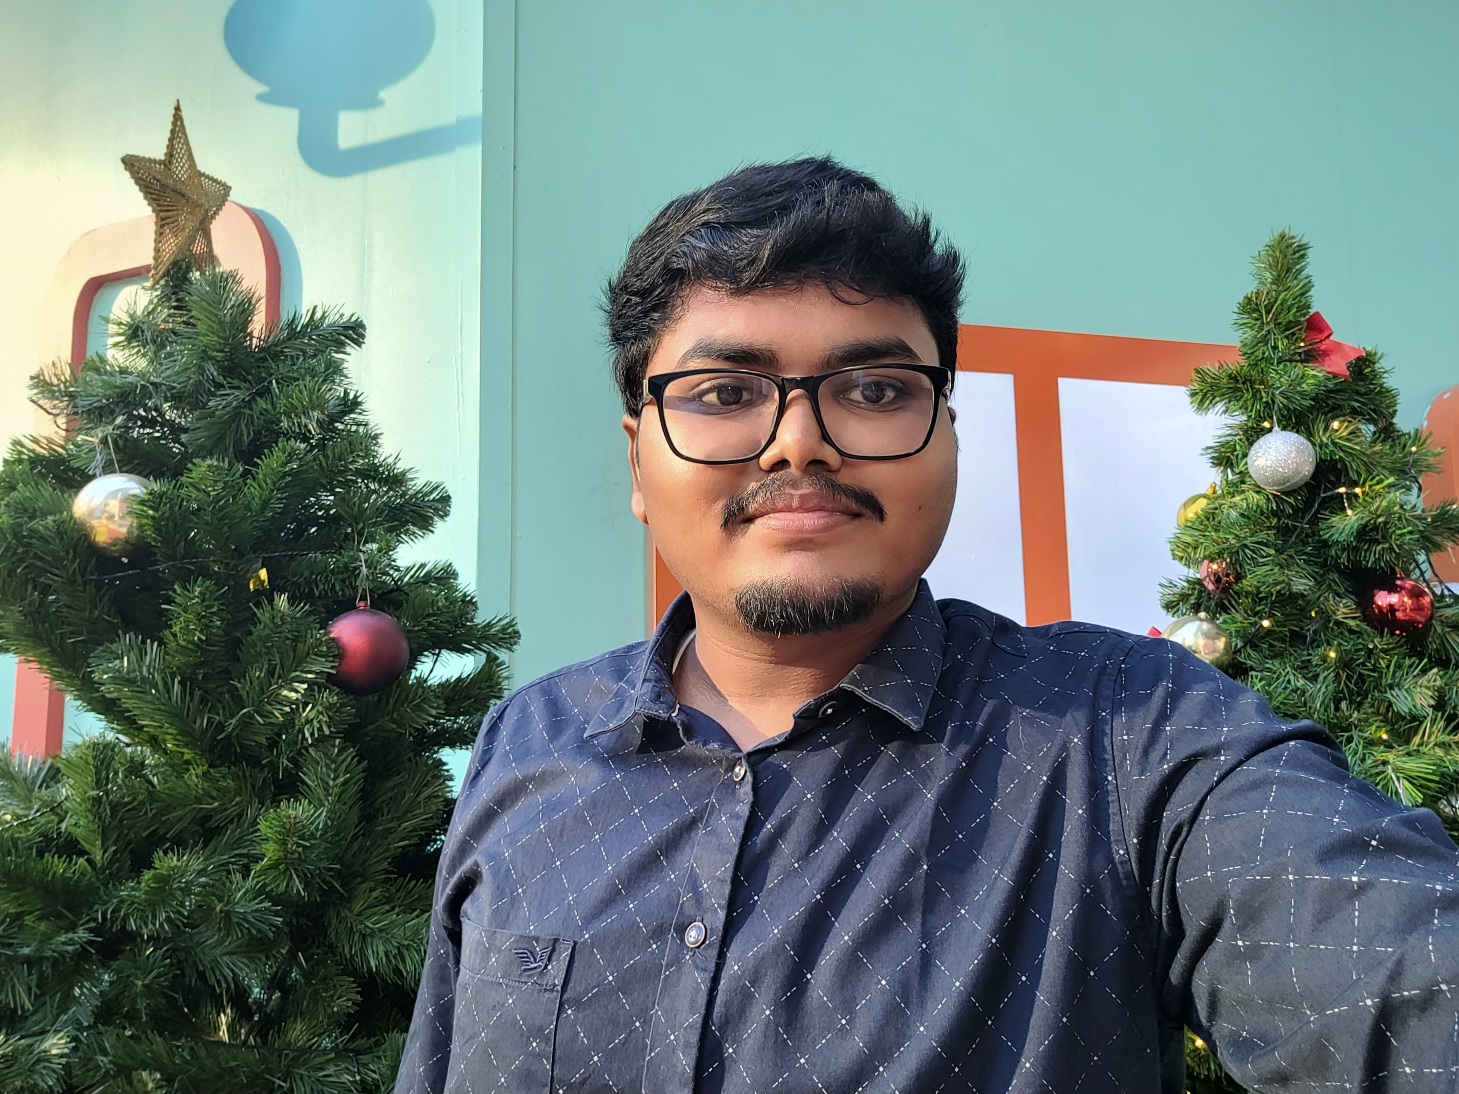
Thilak Raj Murugan
Backend Engineer · Distributed Systems
Technical Skills
Languages
Infrastructure
Data Systems
ML & Tools
“Passionate about petabyte-scale infrastructure!”
Hi, I'm
Thilak Raj Murugan
I'm a Software Engineer with 5+ years of experience in building backend, distributed systems and AI Infrastructure that serve millions of users. I hold a Master's in Data Infrastructure from UW–Madison (Public Ivy).
Across Vimeo, PropertyGuru, Hiver, and American Family Insurance, I've owned work spanning high-throughput user recommendations, billing systems, and cloud-scale ML inference.
- Designing APIs and systems that stay fast under scale
- Building resilient data paths with observability and automation
- Shipping backend platforms that teams can trust in production
Experience
Building backend and distributed systems for high-scale products, data-heavy workflows, and ML platforms.
- Engineered an AI Inference platform on GCP that autoscales inference across 1M+ BigQuery rows, eliminating infrastructure provisioning friction for AI engineers.
- Developed Infrastructure as Code (IaC) with Terraform, GitLab CI/CD, Docker and Python to provision GCP resources, thus automating the end-to-end deployment pipeline and reducing deployment time by 80%
- Owned a high-throughput user recommendation service serving 10M+ users by designing backend APIs with PHP, MySQL, Memcached, Docker, and Datadog; increased free-to-paid conversion by 20%.
- Optimized RBAC authorization systems by improving MySQL query performance and data access patterns.
- Modernized legacy pages by rebuilding frontend components with React and TypeScript, improving logged-in user experience and increasing user interaction time by 30%.
- Ideated and built a video recommendation service using Hugging Face Sentence Transformers with Python and Go for the Vimeo Jam hackathon.
- Built and scaled multiple backend microservices using Nest.js, Node.js, and Symfony (PHP), serving 11M+ users across the property-tech industry in South-East Asia.
- Reduced config API latency by 25% using Redis caching and automated cache invalidation, improving efficiency for non-engineering teams.
- Built frontend pages and micro-frontends with TypeScript, React, Redux, and Material UI; improved maintainability by adding unit tests with Jest.
- Led the payment platform overhaul, driving 3× ARR growth for the Gmail-based shared inbox product.
- Automated & optimized payment processing using the Stripe SDK across Python and PHP services, leveraging webhooks and RabbitMQ.
- Implemented multi-factor authentication (MFA/SCA) for EU transactions.
Projects
Selected backend, distributed systems, and data engineering projects that demonstrate depth in performance, reliability, and scale.
Distributed KV Store
Replicated each partition with Raft consensus algorithm
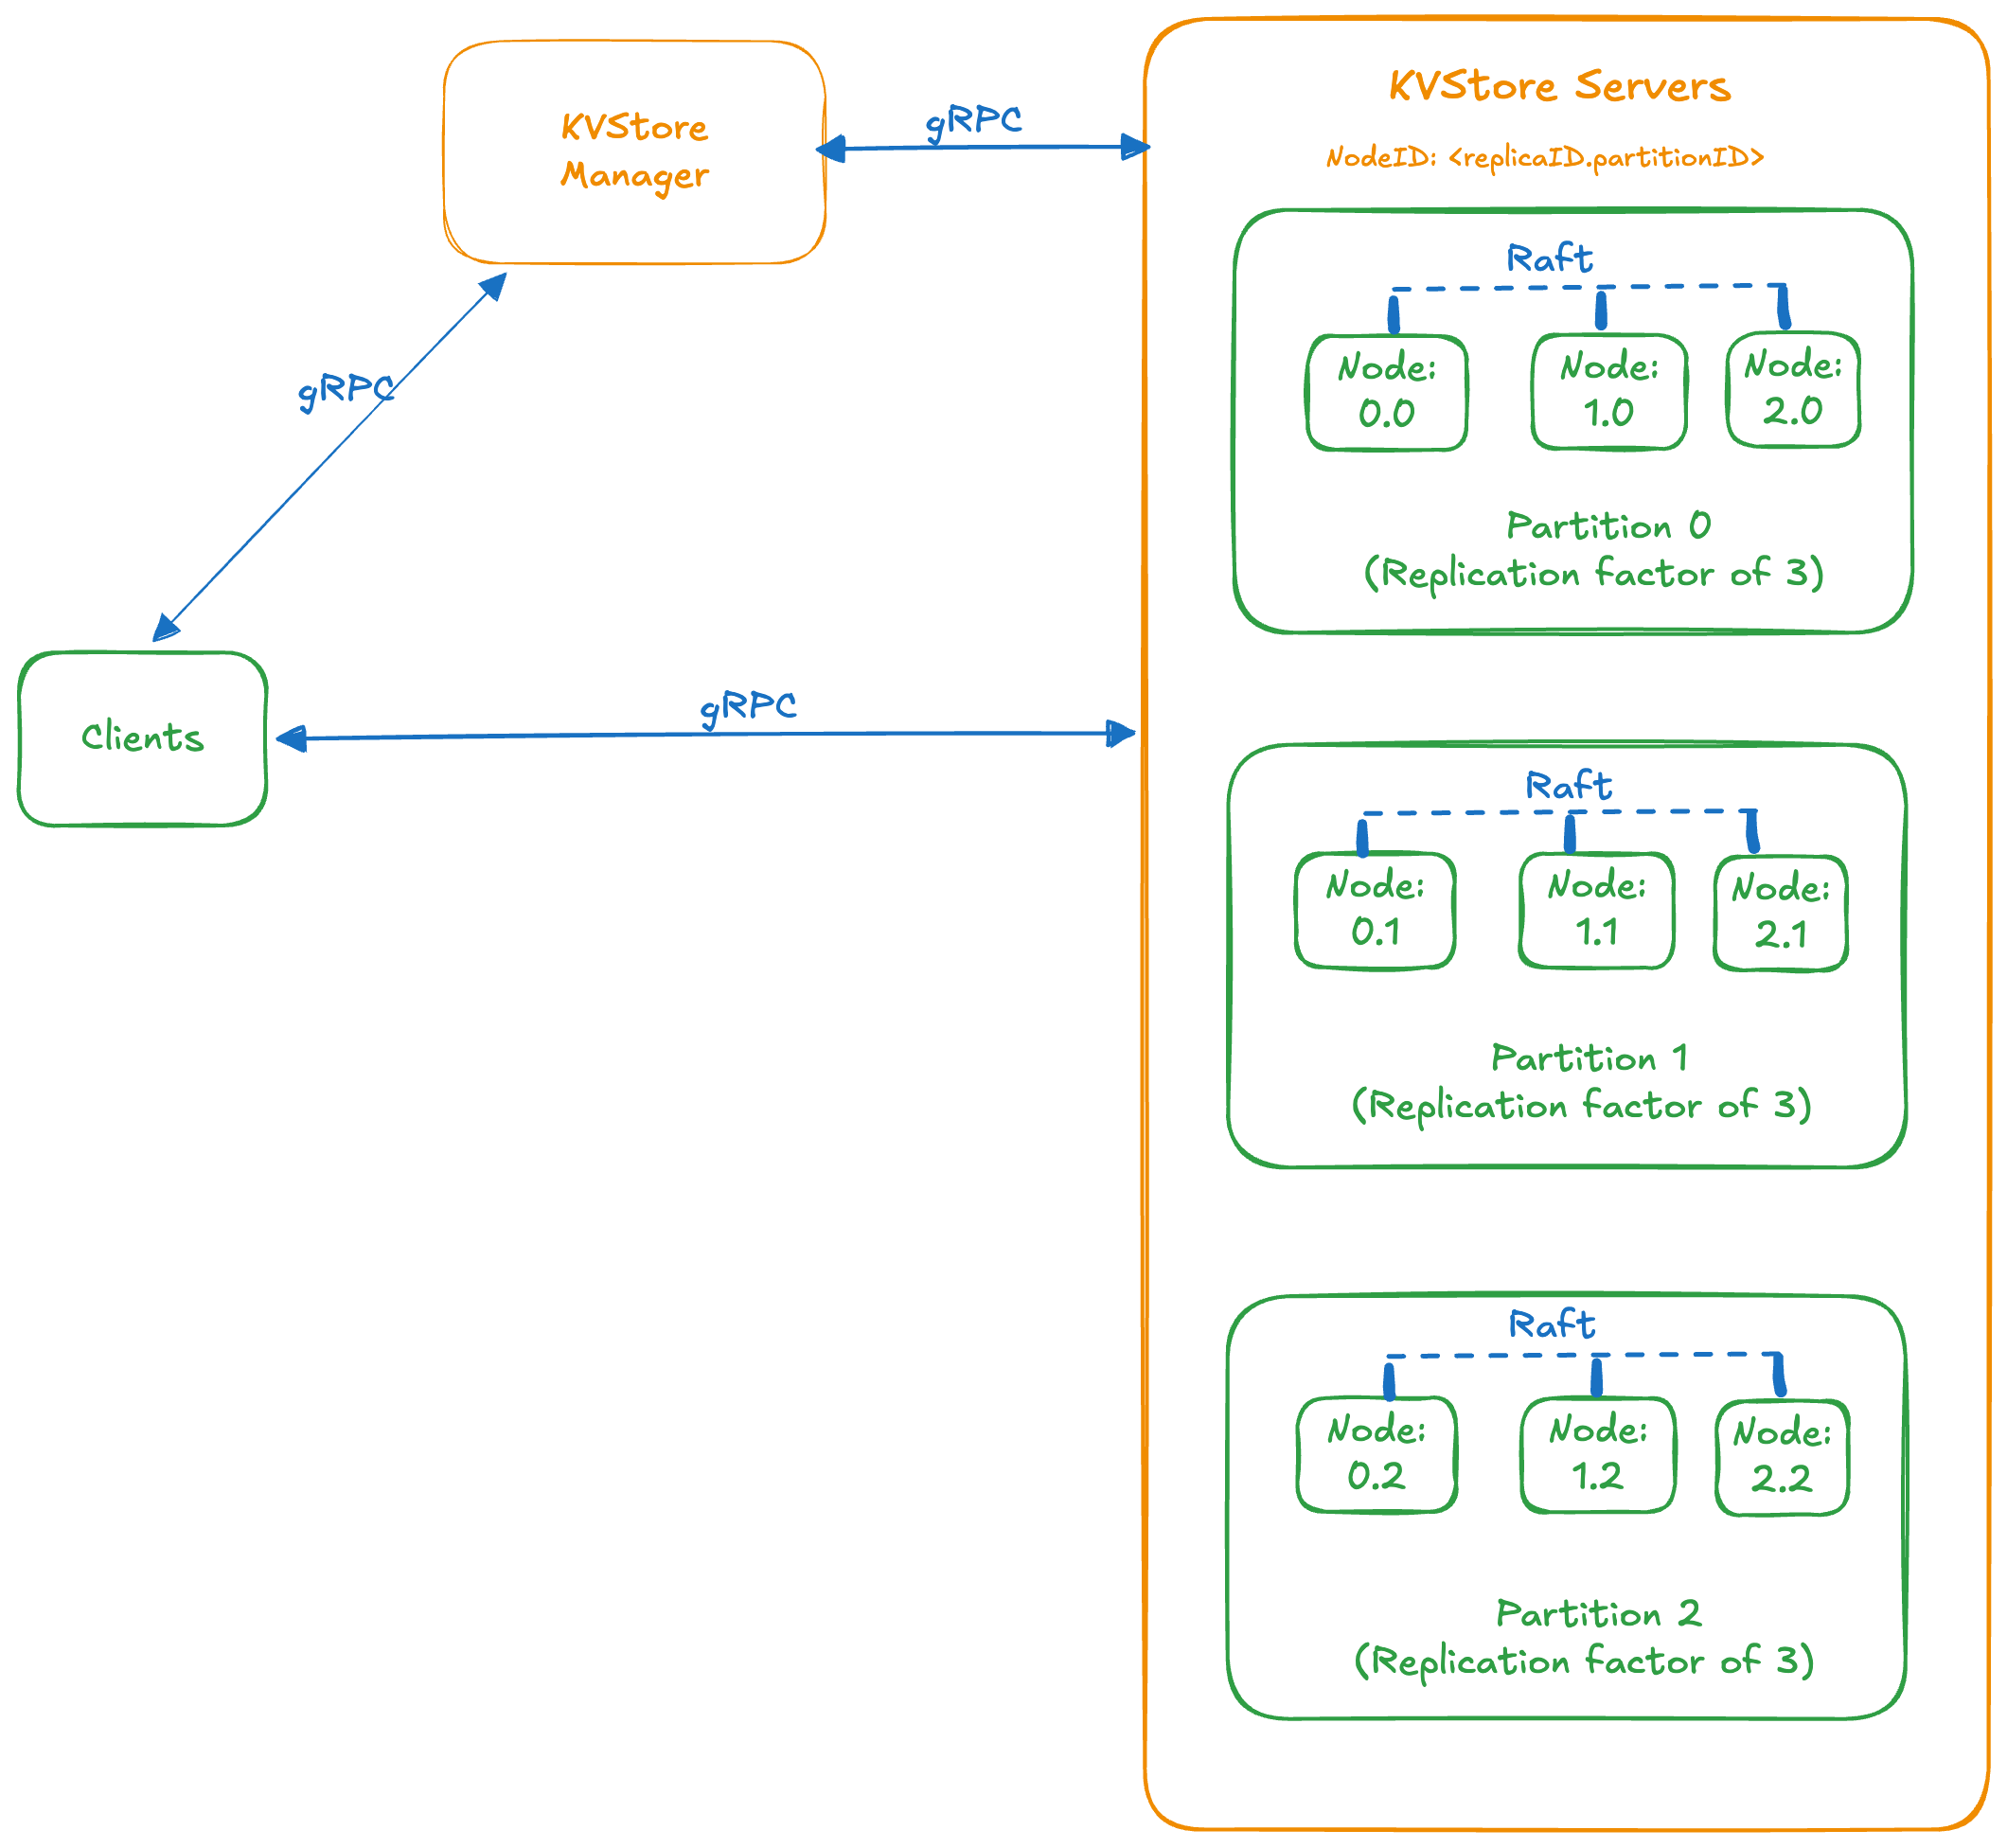
- Built a distributed, fault-tolerant key-value store in Go with horizontal scalability via sharding and Raft-based replication for strong consistency.
- Achieved throughput of 23K ops/sec and made the data durable using bbolt storage engine.
Distributed Database Benchmarking
Performance analysis of TiDB and Cassandra at scale
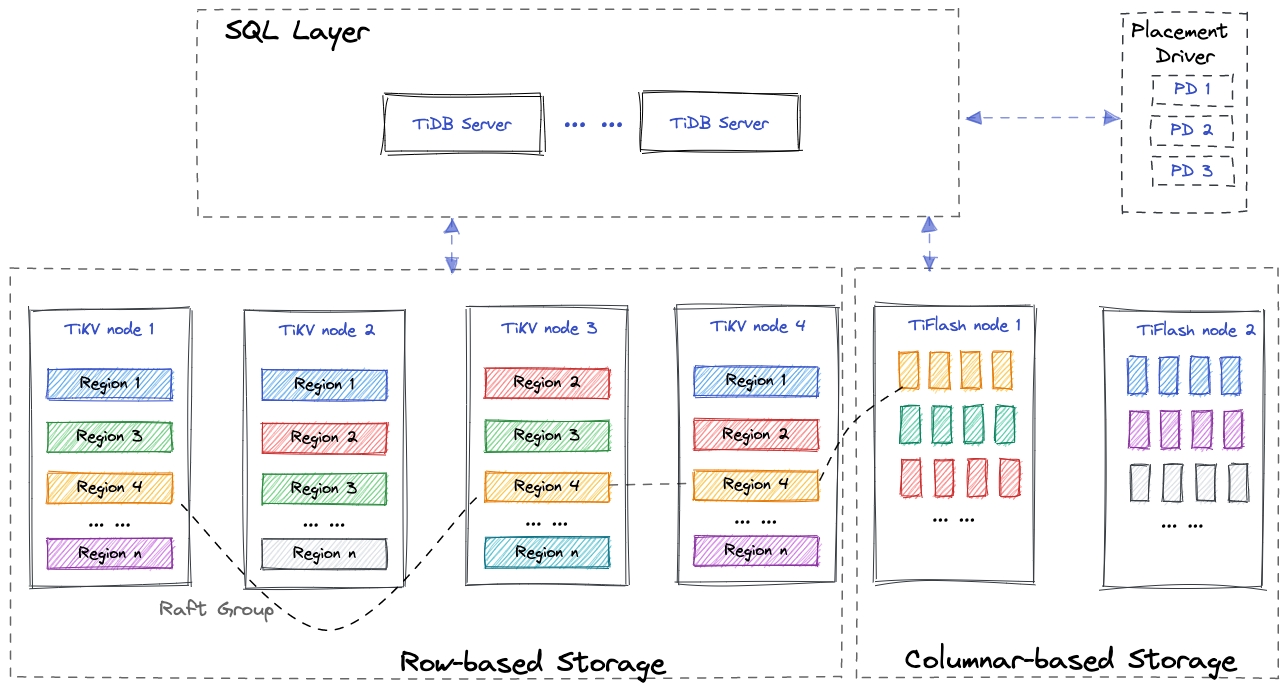
- Benchmarked TiDB with TPC-C/TPC-H workloads up to 190 GiB.
- Ran Cassandra NoSQLBench tests with 200M+ operations.
- Measured throughput, latency (90ms OLTP), and Raft replication lag.
- Cassandra achieved 9K ops/sec with <1ms query latency.
Scalable Data Analytics Pipeline (Batch + Real-Time)
Lambda architecture-based data pipeline for analytics workloads
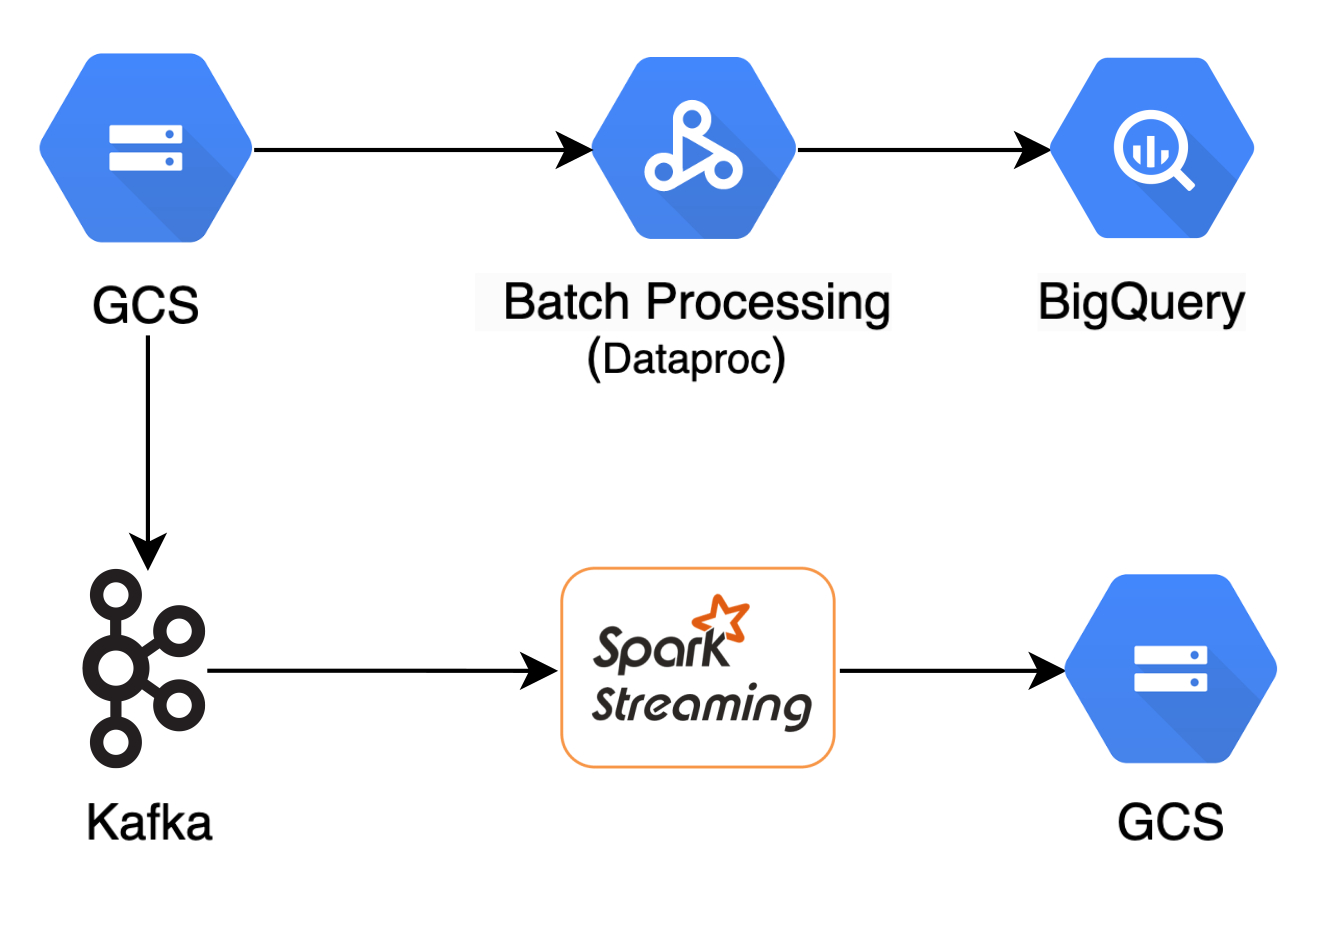
- Designed lambda architecture for NYC Taxi dataset analytics.
- Batch layer: BigQuery and Dataproc for historical processing.
- Streaming layer: Kafka and Spark Streaming for real-time analytics.
- BigQuery scanned 80GiB in <10s using columnar storage.
ML Inference on Google Cloud
Production batch inference infrastructure
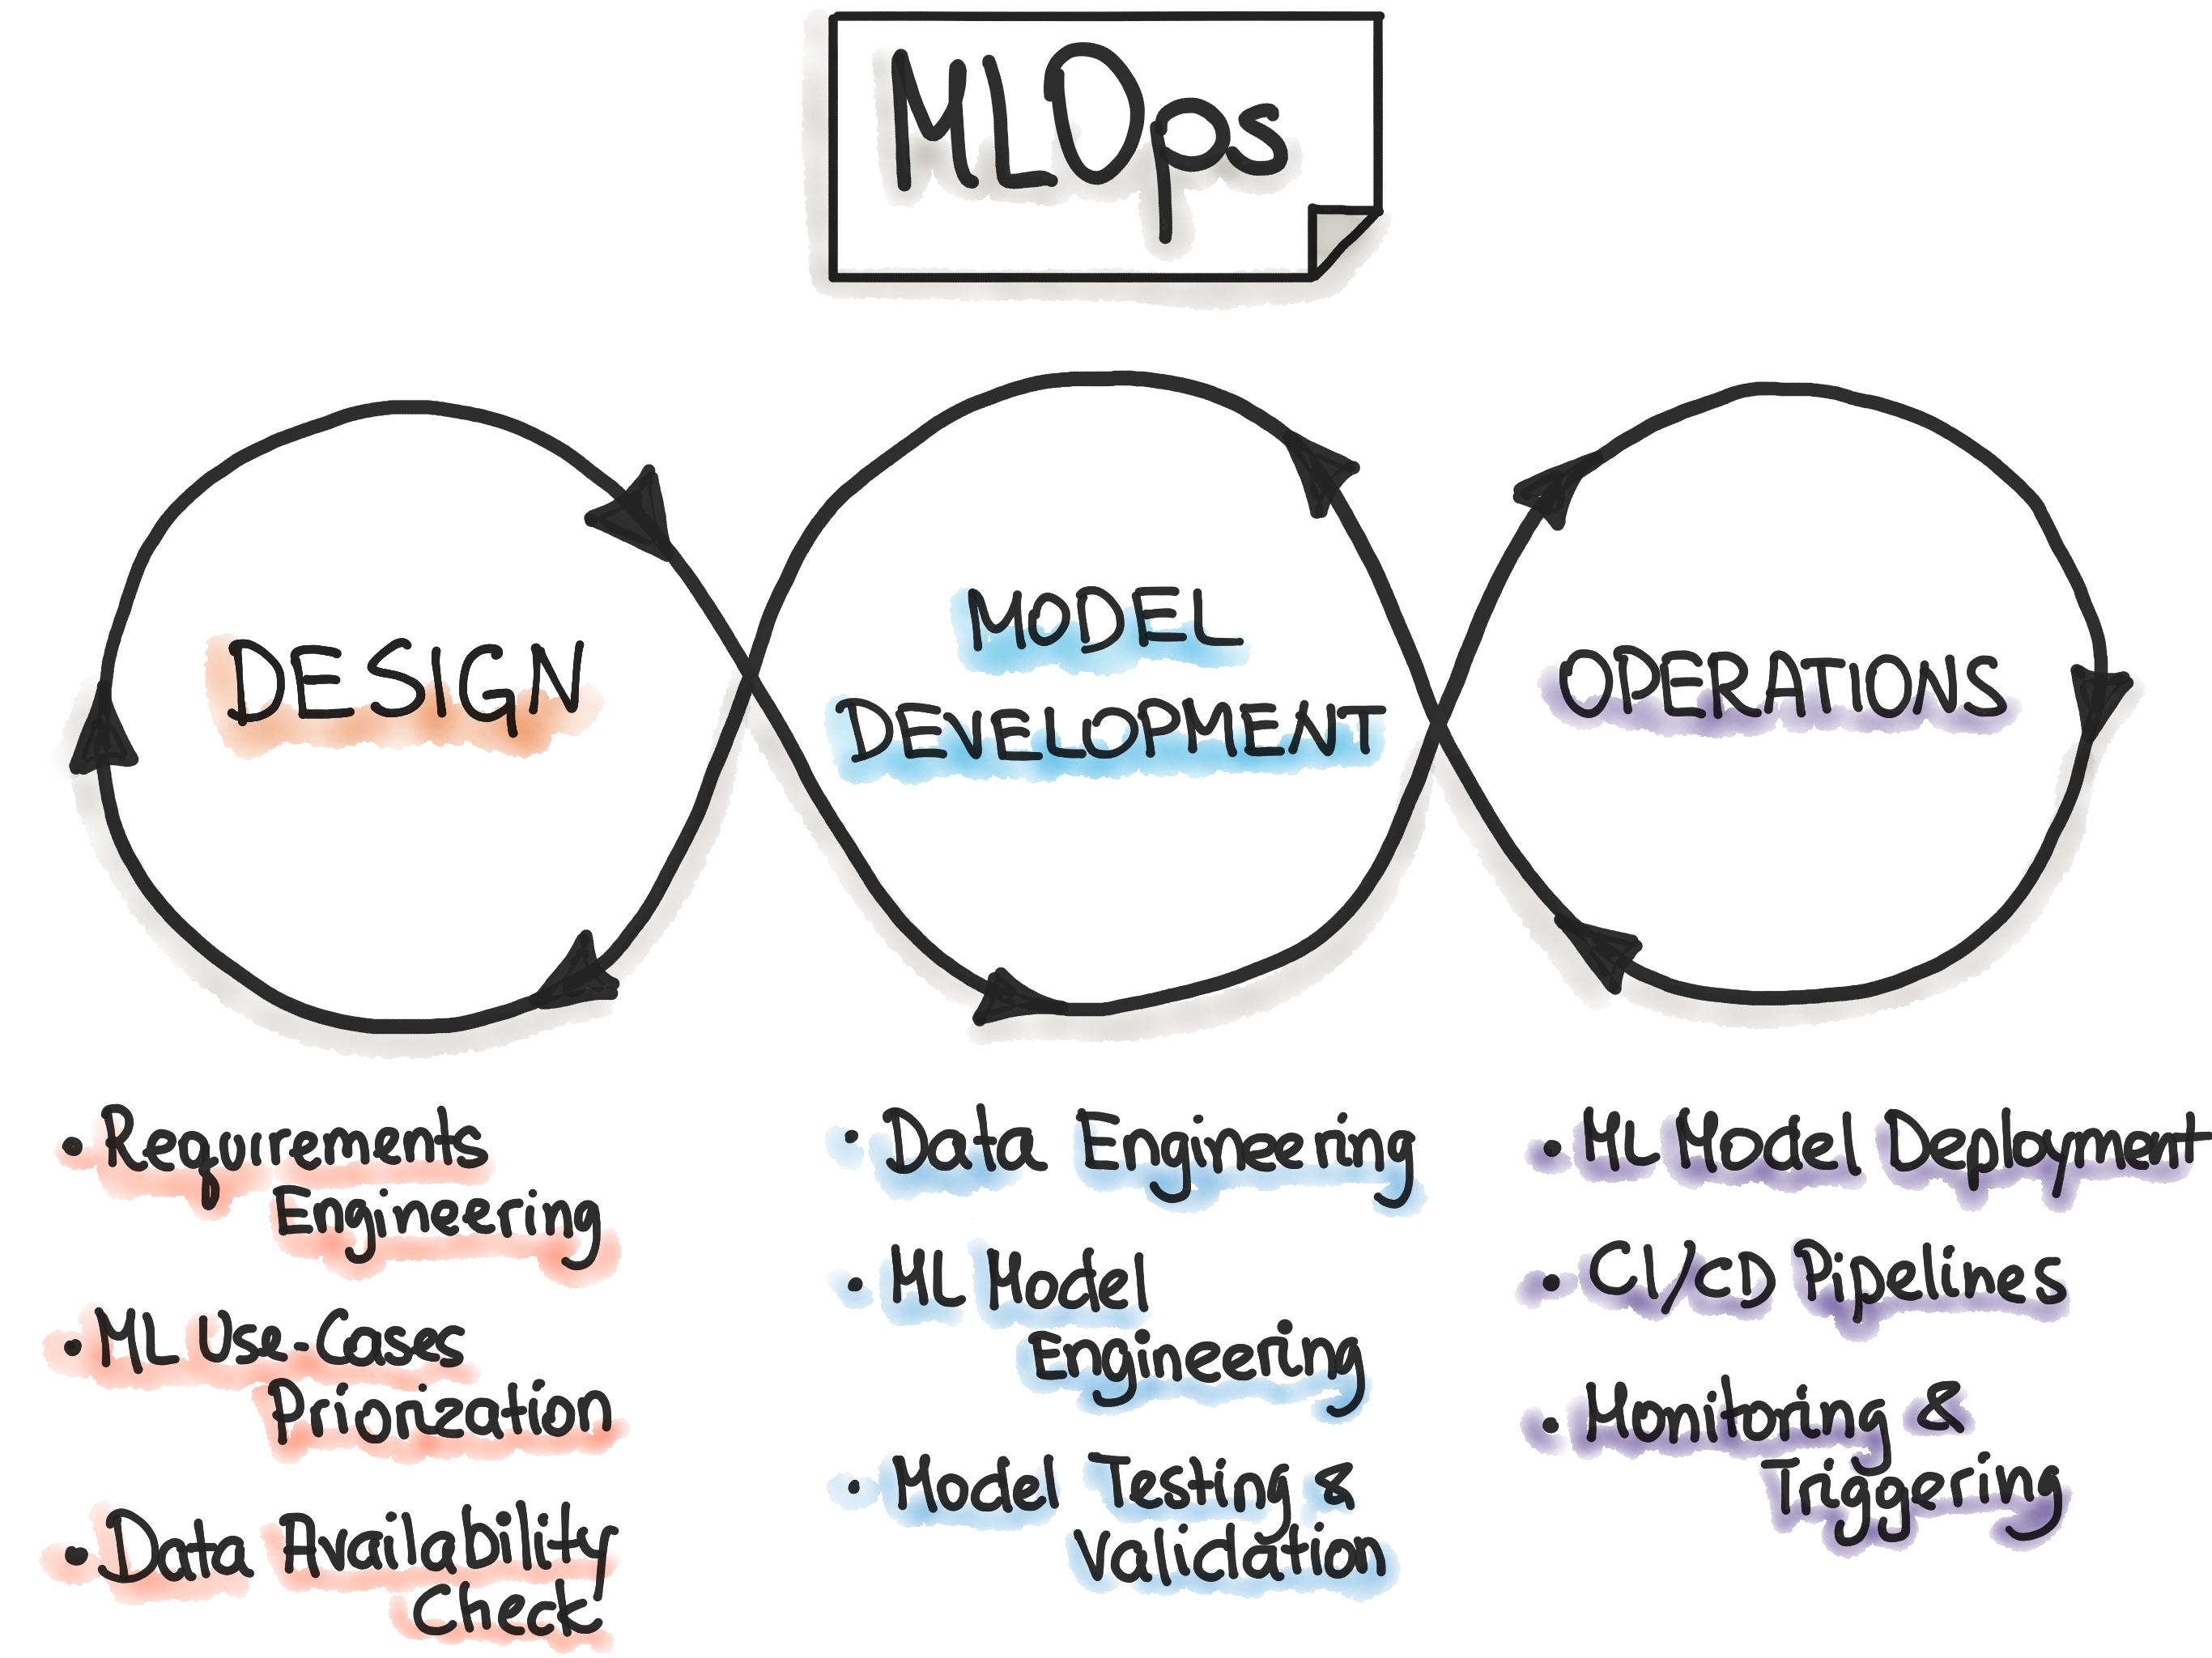
- Built ML inference pipeline on Google Batch service. Scaled to 1M+ BigQuery rows per run.
- Provisioned infrastructure with Terraform (GCS Buckets, Cloud Scheduler, Functions)
- Automated CI/CD with GitLab.
Coding Profiles
Engineering footprint beyond the resume
I actively publish code, solve problems, and contribute to open-source projects. These profiles reflect my passion for backend engineering, distributed systems, and practical software craftsmanship.
Open Source Contribution
Pull Request: openfga/sample-stores#23
Briefly, OpenFGA is a high-performance and flexible authorization and permission system built for developers and inspired by Google Zanzibar. It is currently accepted into the Cloud Native Computing Foundation (CNCF).
Ref: CNCF OpenFGA Project
Skills
Core toolkit I use to build reliable backend systems, data infrastructure, and production ML pipelines.
Languages
Infrastructure
Data Systems
ML & Tools
Contact
Let's build something reliable at scale
I'm seeking full-time backend, distributed systems, and data platform roles starting in 2026.